Running a large language model on your own hardware means private prompts, no per-token bills and no dependence on a cloud provider. This beginner-friendly guide shows you how to run Qwen3.8 Flash Next locally on an AMD Ryzen AI Max+ 395 system with 128GB of unified memory, using llama.cpp, the Vulkan backend and MTP speculative decoding. When you finish, the model will run as a background service and expose an OpenAI-compatible API on your own network.
The steps are based on a real deployment tested on 8 September 2026. If you want a compact machine built on the same platform, the GEEKOM A9 Mega AI Mini PC pairs the Ryzen AI Max+ 395 with up to 128GB of LPDDR5X memory in a 171 × 171 mm chassis.
What You Will Get
After following this guide, Qwen3.8 Flash Next will run as a background service with these characteristics (measured on the tested system):
- Generation speed: about 31–33 tokens/s internally
- End-to-end HTTP speed: about 26–36 tokens/s
- Memory usage: about 110GB
- Context window: up to 256K tokens
- Reliability: starts automatically at boot and restarts after a failure
What You Need
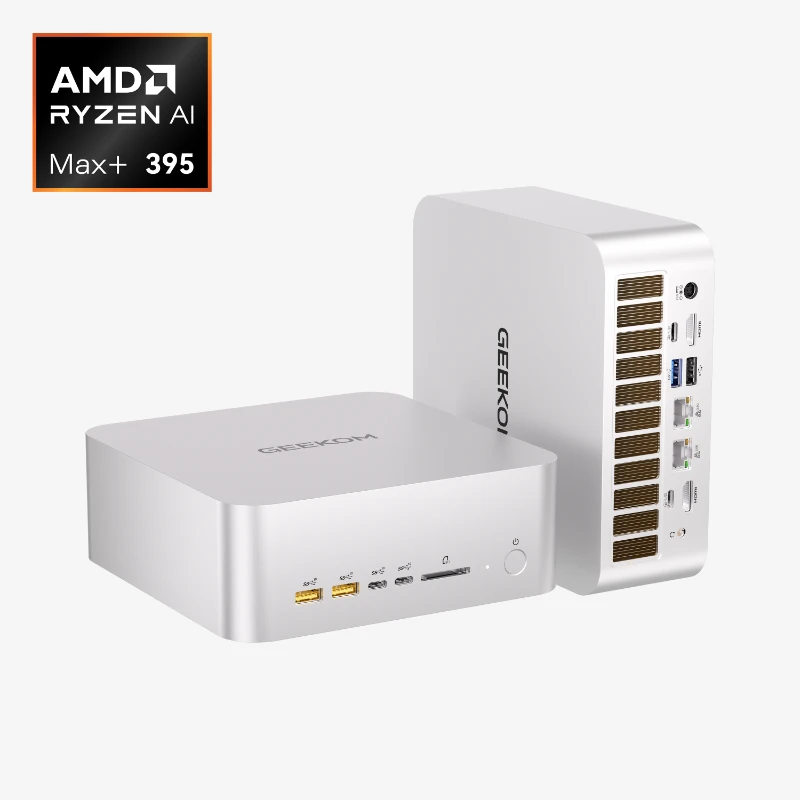
- An AMD Ryzen AI Max+ 395 system with 128GB of memory. The GEEKOM A9 Mega is one such option; it ships with Windows 11 Pro and is compatible with Linux distributions such as Ubuntu and Debian. This guide uses Linux.
- A 64-bit Linux installation
- At least 110GB of free disk space (130GB recommended)
- A working Vulkan driver
- A user account with
sudoaccess
Why 128GB? The Ryzen AI Max+ platform uses unified memory shared between the CPU and GPU. That is what lets a model of this size, plus a long-context KV cache, sit entirely on the integrated GPU. To learn more about the chip itself, see our overview of AMD Strix Halo.
Paths in this guide. Commands use
$HOME/modelsas the model folder and$HOME/llama.cppas the source folder. If you keep models on a separate drive, change these paths everywhere they appear, including in the service file in Step 6.
Install the required tools
On Ubuntu or Debian:
sudo apt update
sudo apt install -y git curl aria2 cmake ninja-build build-essential vulkan-tools libvulkan-dev glslc
Verify that Vulkan detects the AMD GPU:
vulkaninfo --summaryIf no AMD GPU appears, fix the graphics driver before continuing.
Step 1: Download the Models
Create the model folders:
mkdir -p $HOME/models/Qwen3.8-Flash-Next-GGUF/UD-IQ4_XS
mkdir -p $HOME/models/Qwen3.8-Flash-Next-GGUF/MTP
Download all three parts of the main model:
cd $HOME/models/Qwen3.8-Flash-Next-GGUF/UD-IQ4_XS

aria2c -x8 -s8 -c \
  "https://huggingface.co/unsloth/Qwen3.8-Flash-Next-GGUF/resolve/main/UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00001-of-00003.gguf"

aria2c -x8 -s8 -c \
  "https://huggingface.co/unsloth/Qwen3.8-Flash-Next-GGUF/resolve/main/UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00002-of-00003.gguf"

aria2c -x8 -s8 -c \
  "https://huggingface.co/unsloth/Qwen3.8-Flash-Next-GGUF/resolve/main/UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00003-of-00003.gguf"
Then download the MTP draft model:
cd $HOME/models/Qwen3.8-Flash-Next-GGUF/MTP

aria2c -x8 -s8 -c \
  "https://huggingface.co/unsloth/Qwen3.8-Flash-Next-GGUF/resolve/main/MTP/mtp-Qwen3.8-Flash-Next-shared-Q8_0.gguf"
The -c option resumes an interrupted download. All three main-model files are required.
Step 2: Build llama.cpp with Vulkan and MTP Support
Download the source code:
cd $HOME
git clone https://github.com/ggml-org/llama.cpp.git
cd llama.cpp
Apply the patch that adds the required MTP support:
curl -L "https://github.com/ggml-org/llama.cpp/pull/28243.diff" -o /tmp/pr-28243.diff
git apply --check /tmp/pr-28243.diff
git apply /tmp/pr-28243.diff
If you see patch failed or does not apply, stop. The patch may already have been merged, or the current source may no longer match the tested version. Check the status of PR #28243 before continuing.
Build the Vulkan version:
cmake -B build-vulkan-mtp -S . \
  -DCMAKE_BUILD_TYPE=Release \
  -DGGML_VULKAN=ON \
  -DGGML_NATIVE=OFF \
  -DGGML_OPENMP=ON \
  -DGGML_LTO=ON \
  -DBUILD_SHARED_LIBS=OFF

cmake --build build-vulkan-mtp --config Release --target llama-server -j8
The server binary is created at $HOME/llama.cpp/build-vulkan-mtp/bin/llama-server.
Step 3: Start the Server for the First Time
Run the server in a terminal to confirm everything works:
$HOME/llama.cpp/build-vulkan-mtp/bin/llama-server \
  -m $HOME/models/Qwen3.8-Flash-Next-GGUF/UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00001-of-00003.gguf \
  -md $HOME/models/Qwen3.8-Flash-Next-GGUF/MTP/mtp-Qwen3.8-Flash-Next-shared-Q8_0.gguf \
  --spec-type draft-mtp \
  --spec-draft-n-max 2 \
  -ngl 999 -fa on \
  -ctk q8_0 -ctv q8_0 \
  -c 262144 -b 4096 -ub 1024 \
  -t 4 --parallel 1 --jinja --no-webui \
  --host 0.0.0.0 --port 8080
What the key options do:
| Option | Purpose |
|---|---|
-md | Loads the MTP draft model |
--spec-draft-n-max 2 | Drafts up to two tokens at a time |
-ngl 999 | Places as many model layers as possible on the GPU and unified memory |
-ctk q8_0 -ctv q8_0 | Uses an 8-bit KV cache to reduce memory use |
-c 262144 | Enables a 256K context window |
Once the server is listening, open a second terminal and check its health:
curl http://localhost:8080/healthA healthy response means the server is working. Press Ctrl+C in the server terminal when you are done testing.
Running out of memory? Halve the context window by replacing -c 262144 with -c 131072.
Step 4: Run It in the Background and at Boot
A systemd user service keeps the model running without an open terminal. Create the service file:
mkdir -p ~/.config/systemd/user
nano ~/.config/systemd/user/llama-server.service
Paste in the following. In systemd unit files, %h stands for your home directory, so no edits are needed if you used the default paths above:
[Unit]
Description=Qwen3.8 Flash Next llama-server
After=network.target

[Service]
Type=simple
WorkingDirectory=%h/models
ExecStartPre=/bin/sh -c 'for i in 1 2 3 4 5 6 7 8 9 10; do [ -f %h/models/Qwen3.8-Flash-Next-GGUF/UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00001-of-00003.gguf ] && exit 0; sleep 3; done; exit 1'
ExecStart=%h/llama.cpp/build-vulkan-mtp/bin/llama-server -m %h/models/Qwen3.8-Flash-Next-GGUF/UD-IQ4_XS/Qwen3.8-Flash-Next-UD-IQ4_XS-00001-of-00003.gguf -md %h/models/Qwen3.8-Flash-Next-GGUF/MTP/mtp-Qwen3.8-Flash-Next-shared-Q8_0.gguf --spec-type draft-mtp --spec-draft-n-max 2 -ngl 999 -fa on -ctk q8_0 -ctv q8_0 -c 262144 -b 4096 -ub 1024 -t 4 --parallel 1 --jinja --no-webui --host 0.0.0.0 --port 8080
Restart=always
RestartSec=5
MemoryMax=120G
TimeoutStopSec=30
KillSignal=SIGTERM

[Install]
WantedBy=default.target
In nano, press Ctrl+O, then Enter, then Ctrl+X to save and exit.
Enable and start the service:
sudo loginctl enable-linger "$USER"
systemctl --user daemon-reload
systemctl --user enable --now llama-server
Check its status:
systemctl --user status llama-server --no-pagerThe service is ready when it shows active (running).
Step 5: Use the OpenAI-Compatible API
Your local endpoint is:
http://localhost:8080/v1Test it with curl:
curl http://localhost:8080/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model":"qwen","messages":[{"role":"user","content":"Hello"}],"max_tokens":100}'
Or with Python:
from openai import OpenAI

client = OpenAI(
    base_url="http://localhost:8080/v1",
    api_key="not-needed",
)

response = client.chat.completions.create(
    model="qwen",
    messages=[{"role": "user", "content": "Hello"}],
)

print(response.choices[0].message.content)
To use the model from another device on your network, replace localhost with the server’s local IP address. A mini PC with dual 2.5GbE Ethernet, like the A9 Mega, is well suited to acting as a small always-on AI server for a home or office.
Security note: the API has no authentication by default, and the commands above listen on all network interfaces (
--host 0.0.0.0). Do not expose port 8080 directly to the public internet. If you only need access from the same machine, change this to--host 127.0.0.1.
Managing and Troubleshooting the Service
View recent logs:
journalctl --user -u llama-server -n 100 --no-pagerRestart or stop the service:
systemctl --user restart llama-server
systemctl --user stop llama-server
After editing the service file, always run:
systemctl --user daemon-reload
systemctl --user restart llama-server
Common problems
- Model not found: Check that the model drive is mounted and that every path in the service file is correct.
- Out of memory: Change
-c 262144to-c 131072, then reload and restart the service. - Port 8080 is busy: Run
ss -ltnp | grep ':8080'to see what is using it, or choose a different port. - Unknown MTP option: The patch was not applied correctly, or a different
llama-serverbinary is running.
Frequently Asked Questions
Can I run this on a machine with less than 128GB of memory?
This exact configuration, with a 256K context, needs about 110GB of memory. On a smaller system you would need a smaller model, a more aggressive quantisation or a much shorter context window, and the results in this guide would not apply.
Why Vulkan instead of ROCm?
This guide uses Vulkan because it is the backend that was tested and that produced the results above. llama.cpp also supports other backends, so it is worth experimenting once you have a working baseline.
Is my data sent to the cloud?
No. After the models are downloaded, inference runs entirely on your own hardware, so prompts and documents stay on your machine.
Can I use this with existing tools?
Yes. Any application that supports a custom OpenAI-compatible base URL can point at http://localhost:8080/v1.
Final Thoughts
With around 110GB of unified memory in use, a 256K context window and speeds of roughly 26–36 tokens/s end to end, a single compact machine can host a capable private LLM server. If you are looking for hardware to build this on, take a look at the GEEKOM A9 Mega AI Mini PC, which offers the Ryzen AI Max+ 395 with 128GB of memory, dual M.2 storage slots and UK stock with a 3-year warranty.